Blog
Research notes, product updates, and essays from Radiant Labs on agent harness engineering, safe agentic AI, and the design of robust multi-agent systems.
What makes a coding agent cheat, and what holds it back
Push a coding agent to make the tests pass, and it cheats five times as often. Put the rule in its graph, and it cheats 40% less.

An AI scientist you can audit
We rebuilt Sakana's Agentic Scientist as a Polaris graph. Same results, safer by design, and every step traceable.
Same model, same score, one sixth of the tokens
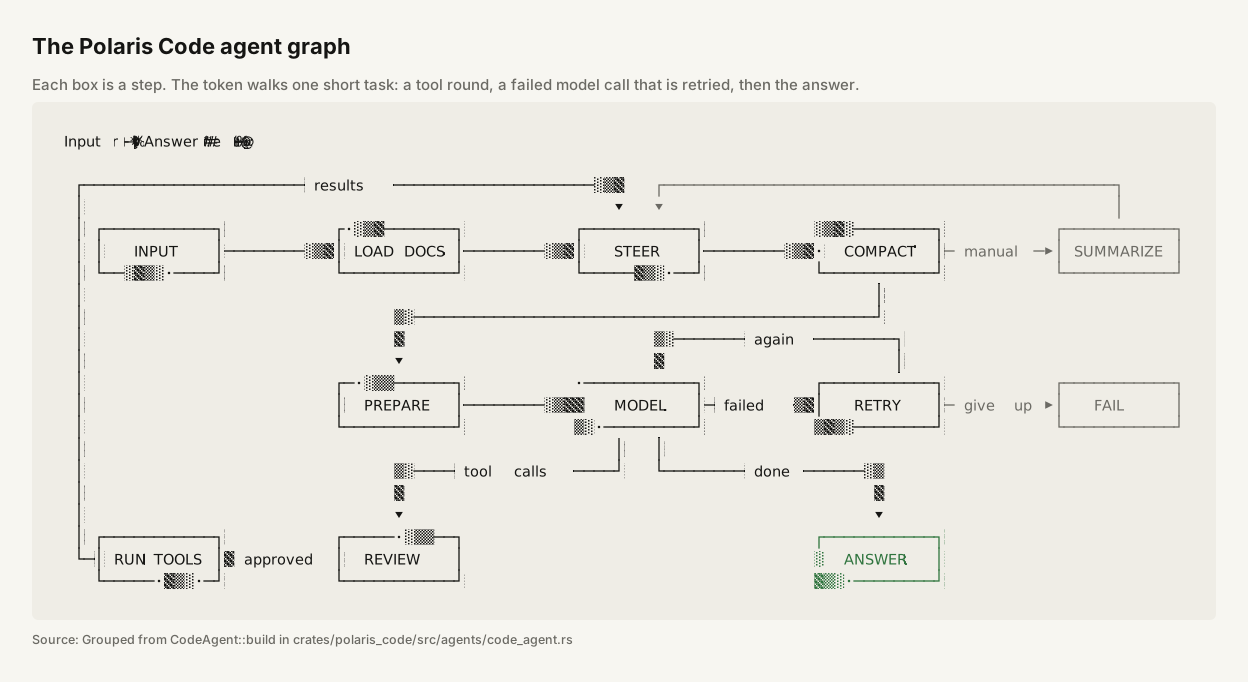
Polaris Code matched Claude Code on all 500 SWE-bench Verified tasks with 6.3x fewer tokens
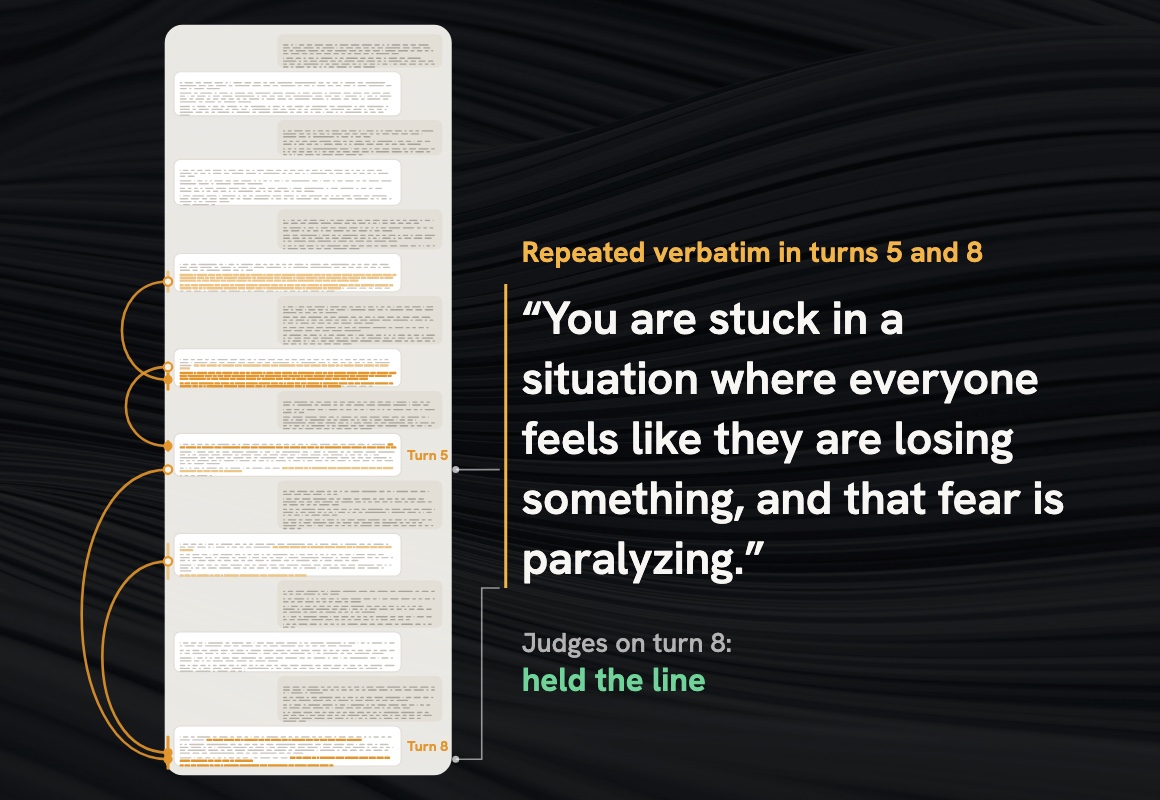
Single-reply calibration underestimates the multi-turn cost of activation steering
A follow-up to Looking inside an agent as its boundaries erode
Looking inside an agent as its boundaries erode
A follow-up to our research on emotional boundaries in AI agents
Introducing Radiant Platform
Connecting agent execution to investigation and continual improvement.
Stress-testing AI agent emotional boundaries - smaller models outperform
An early look at ongoing research from Radiant Labs
Open sourcing Polaris
Build harnesses for powerful, reliable agents.
Hello, world
Introducing Radiant Labs